ysskrishna logoysskrishna

LLM Text Evaluation Framework

LLM Evaluation & Benchmarking App

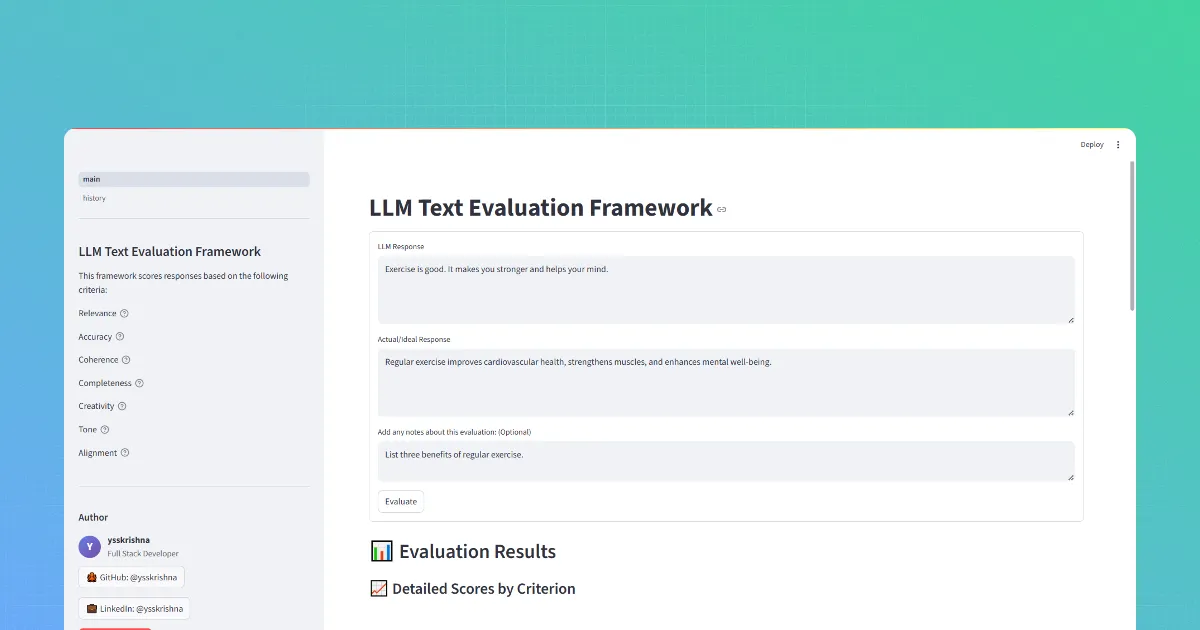
Gallery image 1
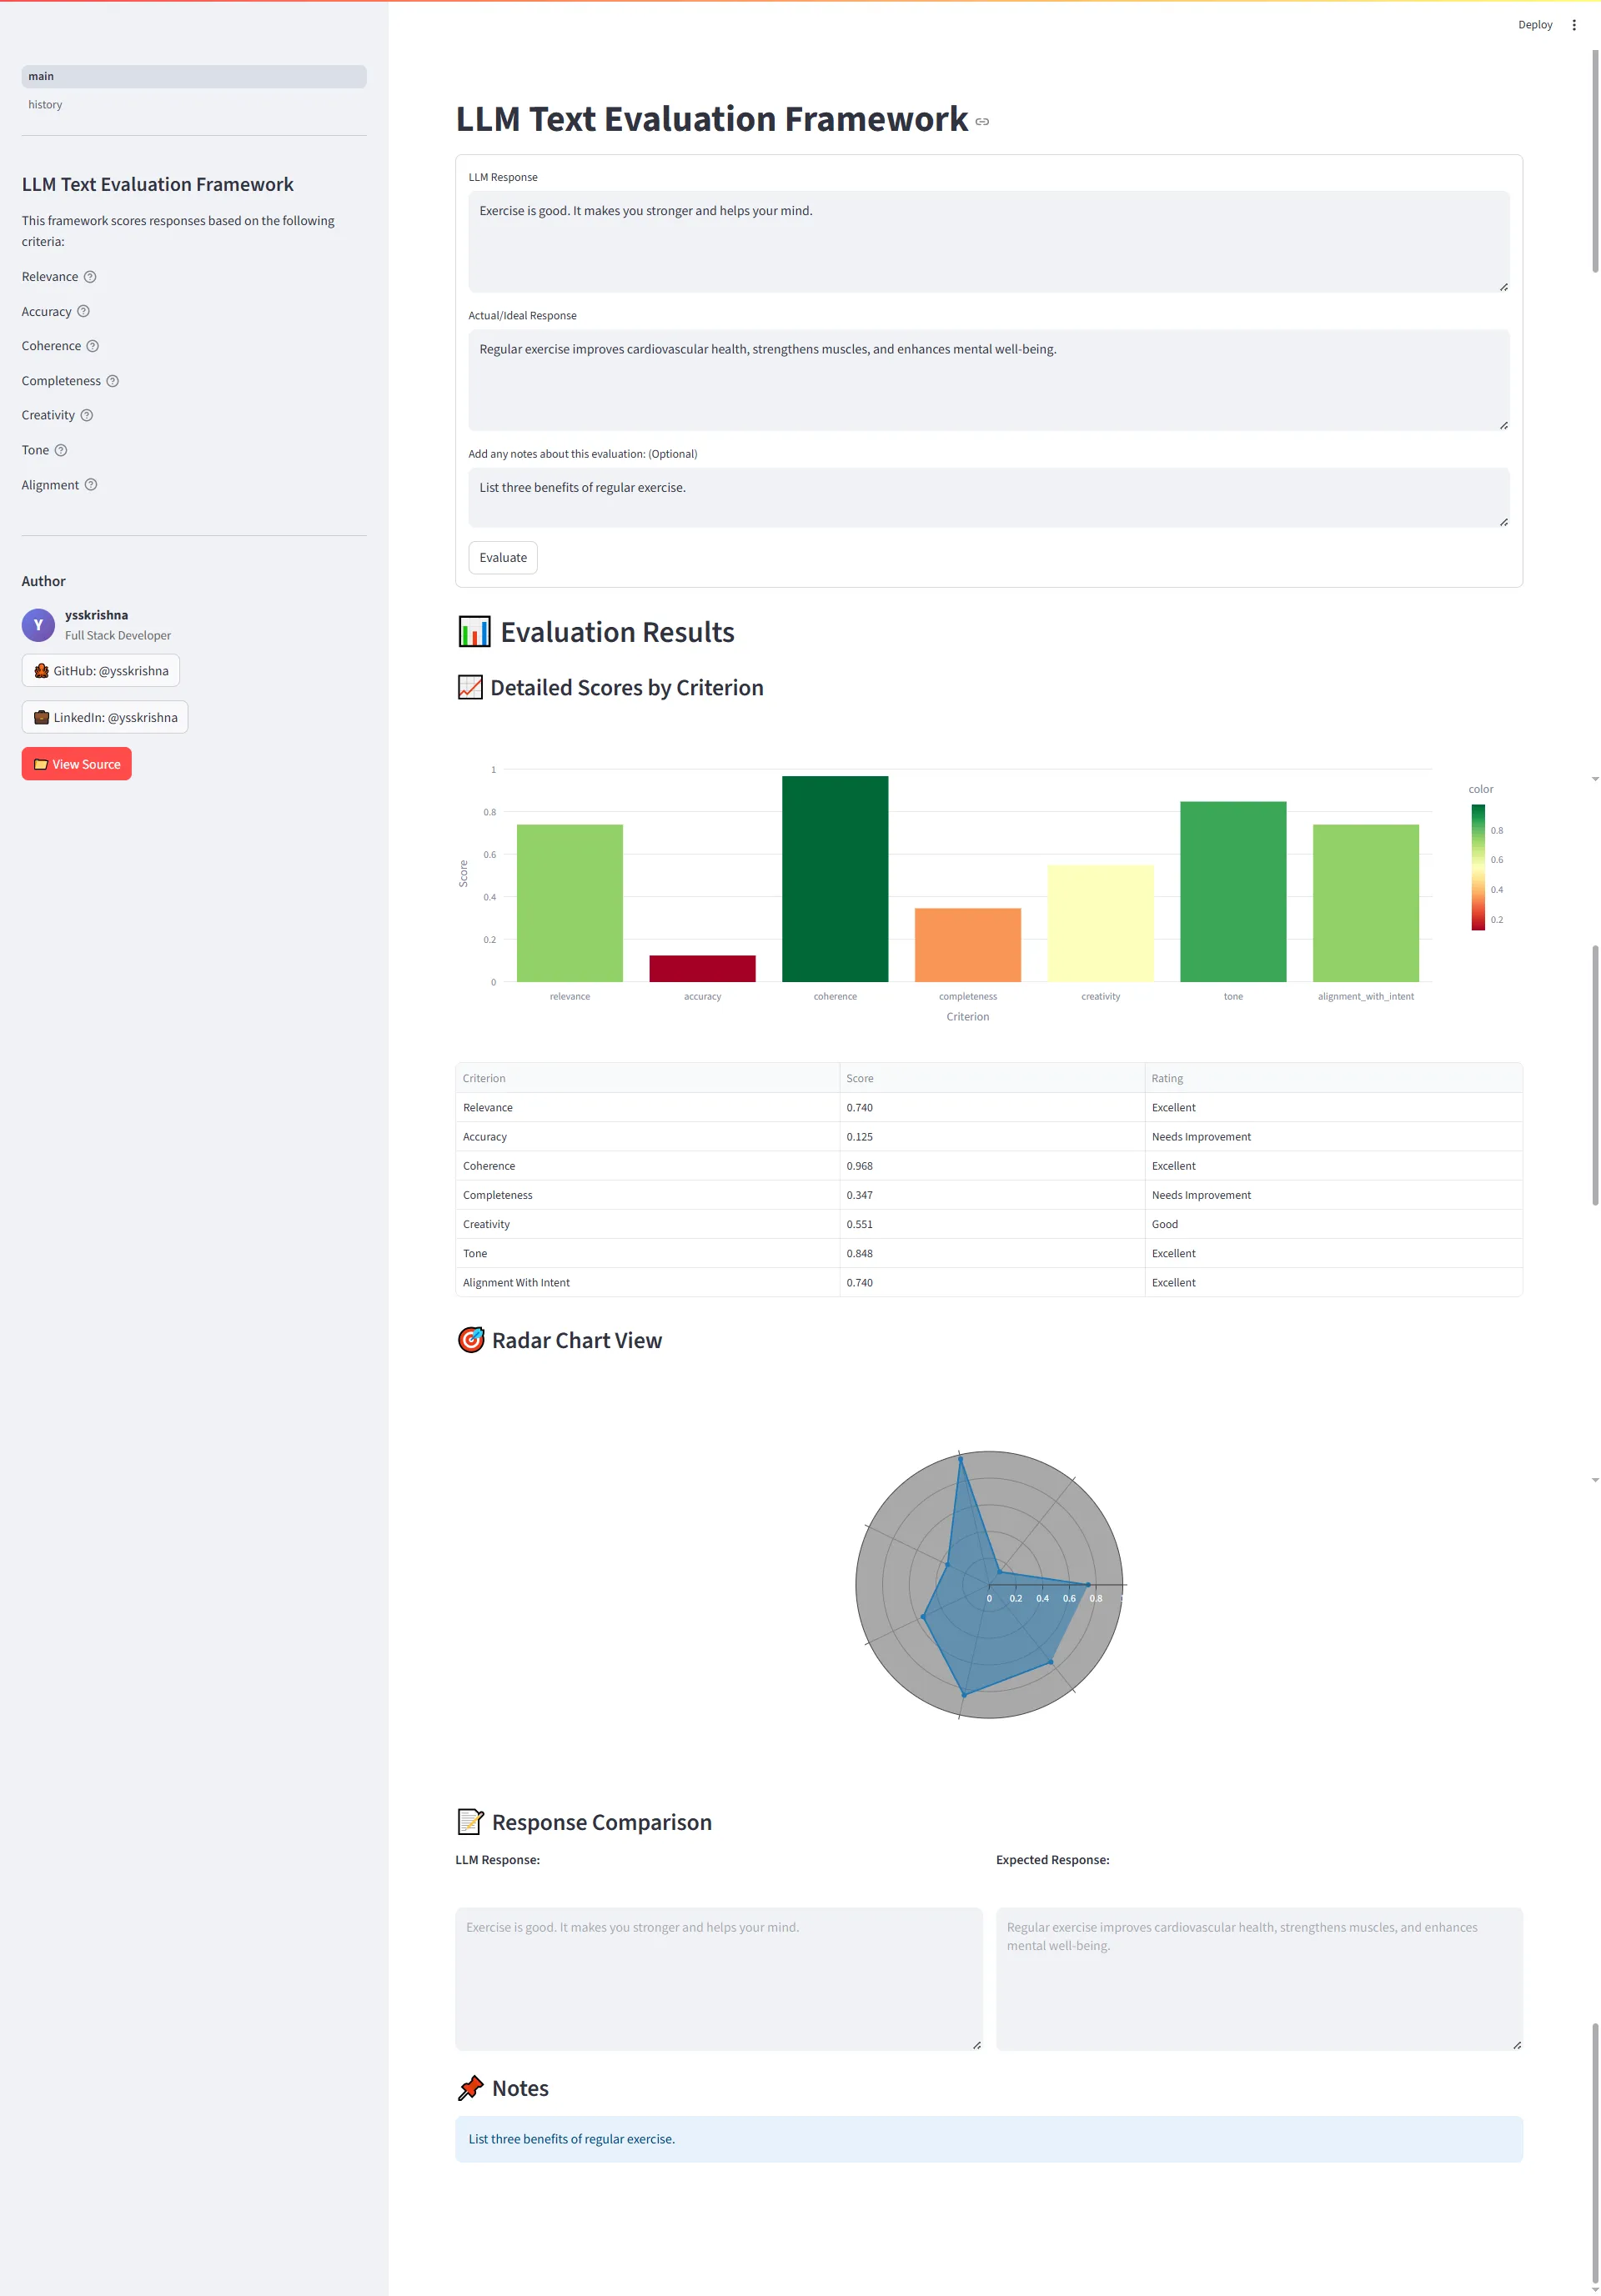
Gallery image 2
Gallery image 3

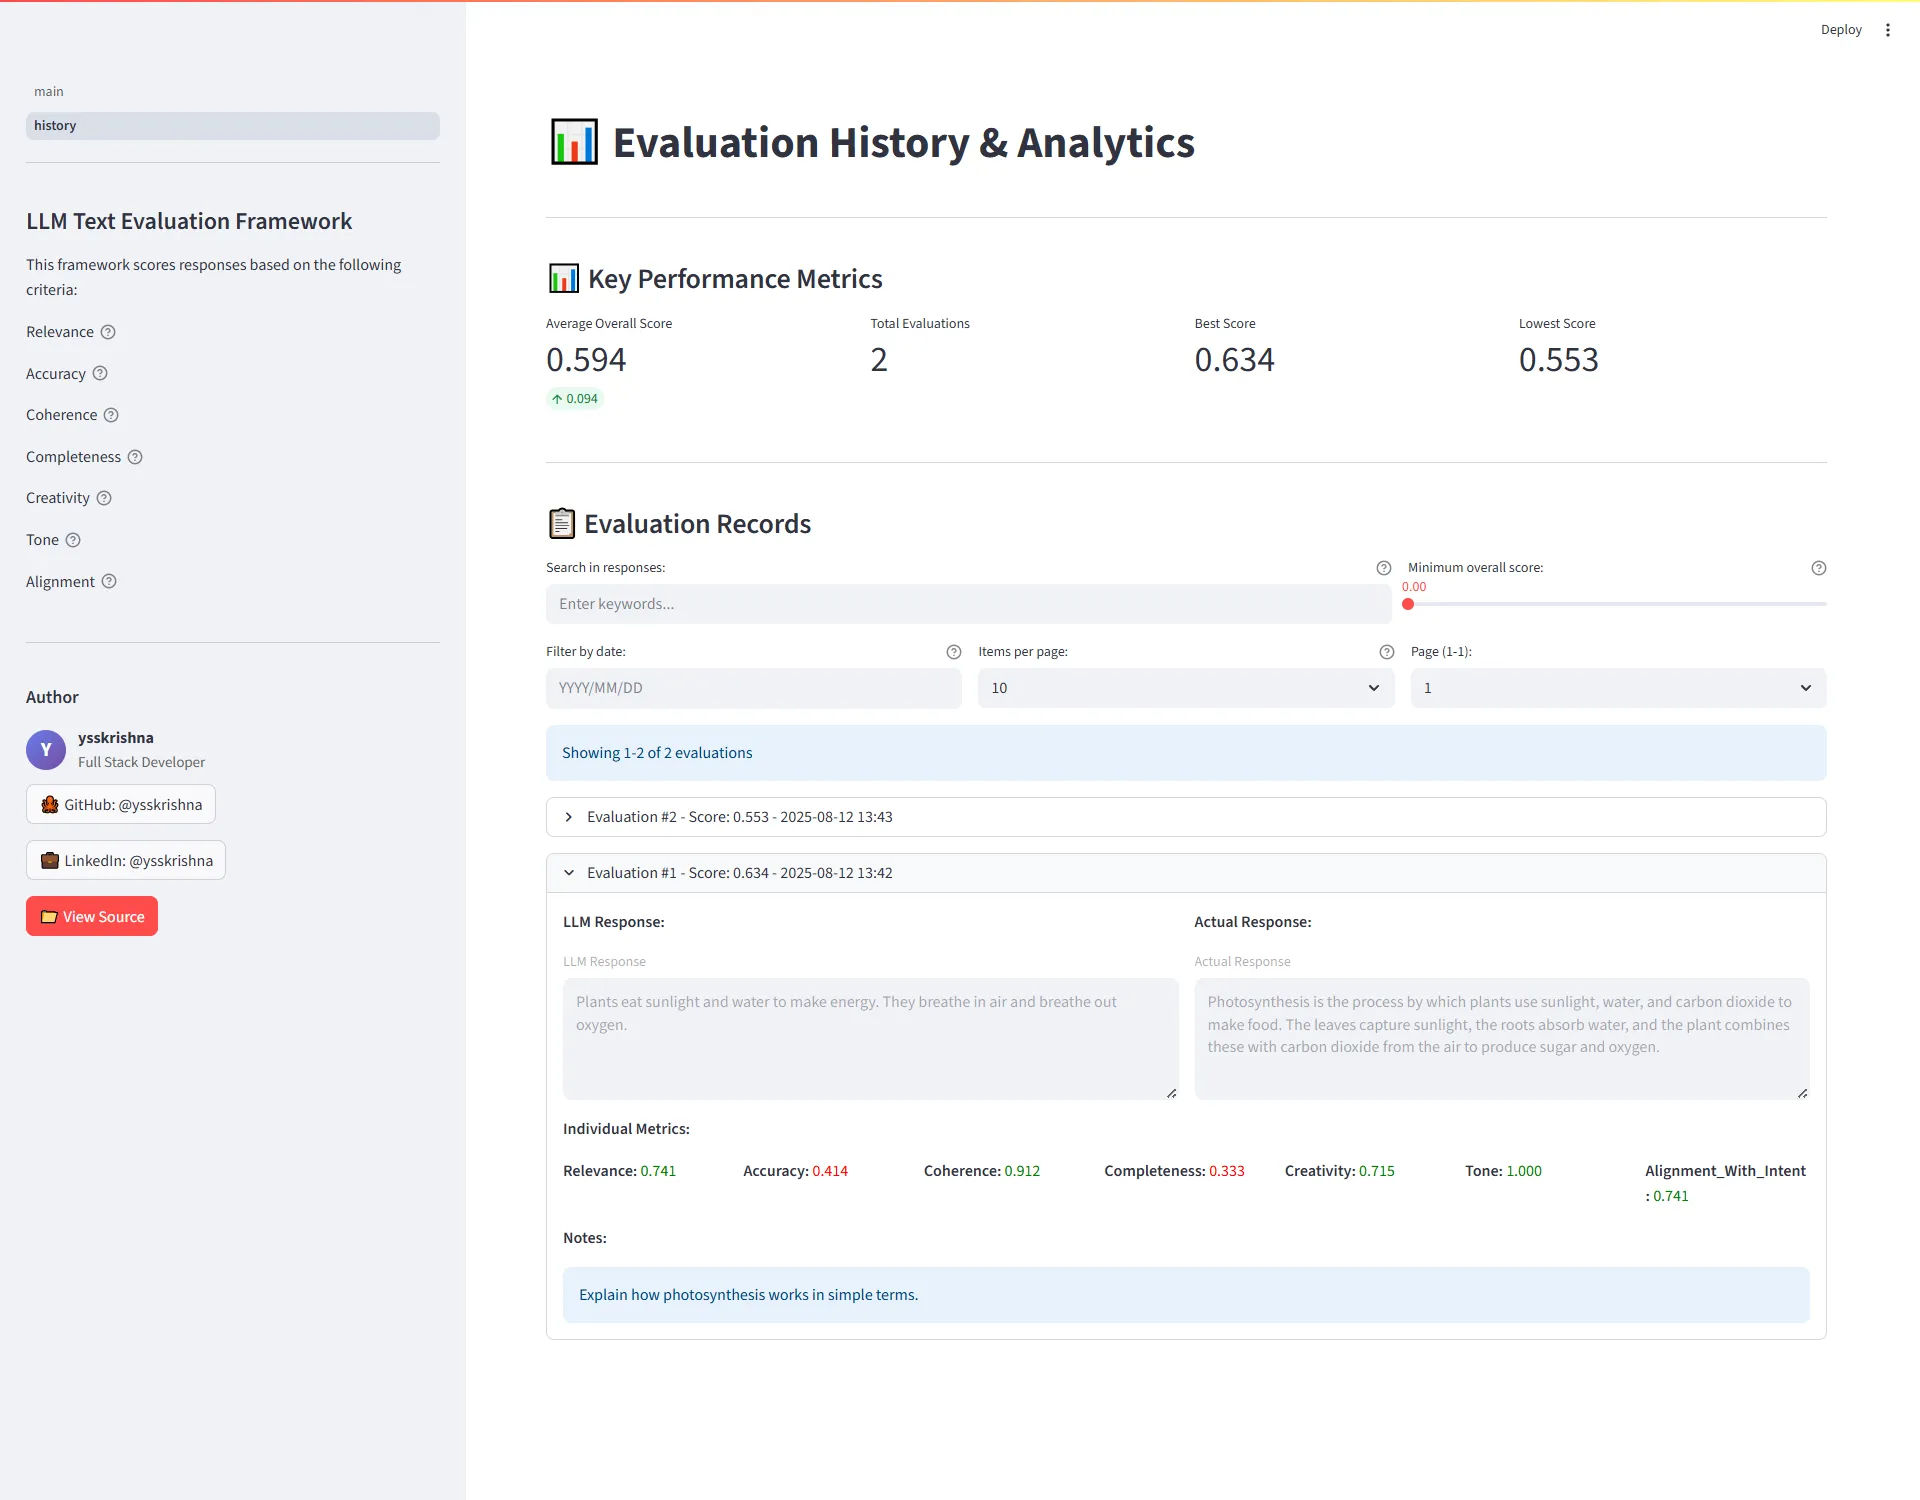
This Streamlit app helps you compare an LLM response to a reference answer using seven weighted dimensions named in the repository (relevance, accuracy, completeness, coherence, creativity, tone, and intent alignment). It stores runs in a SQLite database, shows Plotly visuals, and can be run with Docker or a local Python workflow.

When it is useful

You are benchmarking prompts or models, teaching structured evaluation, or need a repeatable notebook replacement with simple dashboards. It is a lab and QA helper, not an independent judge of truth.

What you can do

  • Enter prompt, model output, and expected answer (terminology follows the app) and inspect per-criterion scores plus charts on the home experience.
  • Open the history view to revisit past evaluations and compare patterns over time.
  • Adjust weights in configuration as documented; criteria importance is configurable, not universal truth.
  • Deploy or develop using the GitHub repository instructions (Docker compose or uv + Streamlit paths).

Limits

  • Scores come from automated heuristics and models (similarity and text stats); they can disagree with human experts or favor certain writing styles.
  • “Accuracy” inside the tool does not verify facts against the world; pair with human review for high-stakes or regulated content.
  • Features marked as future in the README (batch exports, API, etc.) are not promised here.
Frequently asked questions

What does this evaluation app score?

It compares an LLM response to a reference answer across seven weighted criteria: relevance, accuracy, completeness, coherence, creativity, tone, and intent alignment. Results are stored in SQLite with Plotly charts and a history page.

How do I run it?

Python 3.10+. Use docker-compose up --build, or uv sync then uv run streamlit run main.py. Open localhost:8501.

Can I change criterion weights?

Yes. Edit EVALUATION_CRITERIA_WEIGHTS in core/config.py. A settings UI for weights is listed as a future enhancement, not shipped yet.

Do the scores verify real-world facts?

No. Scores use automated heuristics such as Sentence Transformers similarity and NLTK/TextStat stats, so pair with human review for high-stakes content. Batch export and API access are listed as future README items, not shipped.

Continue exploring

ProductAwesome LLM Experiments

Awesome LLM Experiments

Hands-on Python experiments for RAG, embeddings, Chroma, multilingual and multimodal retrieval, and RAGAS evaluation.
Experimental Projects
OpenAI
LangChain
ChromaDB
ToolCover image for AI Token Counter

AI Token Counter

AI token counter with model pricing and context-window comparison in your browser.

Chat & AI
AI Apps & Assistants
+1
BlogCover image for Teach AI Agents to Think From Multiple Angles with Six Thinking Hats Skill

Teach AI Agents to Think From Multiple Angles with Six Thinking Hats Skill

AI Apps & Assistants
Agent Skills
6 min read
ProductAI Agent Skills

AI Agent Skills

Structured thinking skills for AI agents: brainstorming, decision support, and strategy in reusable SKILL.md packs.
Agent Skills
AI Apps & Assistants
Bash
Gemini
BlogCover image for Thinking Skills for AI Agents: From Brainstorming to Critical Analysis

Thinking Skills for AI Agents: From Brainstorming to Critical Analysis

AI Apps & Assistants
Agent Skills
3 min read
BlogCover image for Publish AI Agent Skills to ClawHub: Stop Re-Pasting Your AI Workflow

Publish AI Agent Skills to ClawHub: Stop Re-Pasting Your AI Workflow

AI Apps & Assistants
Agent Skills
3 min read